GPT-6.1 Sol: Benchmarks, Pricing, API, and the New Routing Math
Seven days ago, the practical OpenAI routing ladder looked straightforward: use GPT-6 Luna to try cheaply, use GPT-6 Sol when acceptance mattered, and reserve GPT-6 Astra for the expensive edge where failure cost more than inference.
GPT-6.1 Sol does not destroy that ladder. It changes the point at which a task should climb it.
OpenAI's DevDay model keeps Sol's familiar $2 per million input tokens and $10 per million output tokens for standard requests up to 272K input tokens. The striking change is not the headline tariff. Cached input falls from GPT-6 Sol's $0.20 to $0.10 per million tokens, only five percent of fresh input. OpenAI also claims near-Astra performance on several agentic evaluations at roughly one-fifth of Astra's task cost.
The launch evidence is OpenAI's evidence. The long-context price cliff still reprices the whole request. Tool-heavy agents can spend more on retries and outputs than they save on input. Ultrafast is live for Astra, not yet priced for GPT-6.1 Sol. And the new model is in the API, ChatGPT Work, and Codex, but was not an ordinary Chat model at the September 29 launch cutoff.
The production question is which routes GPT-6.1 Sol has now earned the right to contest.
Key takeaways
GPT-6.1 Sol is available as
gpt-6.1-solin the API and in ChatGPT Work and Codex for eligible paid and organizational plansStandard short-context pricing is $2 input, $0.10 cached input, $2.50 cache write, and $10 output per million tokens
Above 272K input tokens, the entire request moves to $4 input, $0.20 cache read, $5 cache write, and $15 output—not just the excess tokens
OpenAI reports strong agent, coding, document, terminal, and computer-use results, but these are vendor-run launch evaluations rather than an independent verdict
The migration decision should be made on accepted task cost, cache shape, context tier, latency, retries, and human review—not the model name or one benchmark row
Seven-day update: This article updates our GPT-6 Sol and Luna routing guide
On September 22, RohitAI argued that cheaper GPT-6 routes made acceptance rate—not token price—the right optimization target. That principle still holds. GPT-6.1 Sol adds a better cached-input contract and stronger official task-economics claims, so every Sol route deserves a fresh eval rather than an automatic swap. Read the earlier analysis: GPT-6 Sol and Luna Cut the Cost of Trying. Build for Acceptance.
For the rest of the launch, see RohitAI's OpenAI DevDay 2026 guide; this analysis stays with Sol's routing economics.
What launched, exactly?
OpenAI announced GPT-6.1 Sol on September 29, 2026 at DevDay. The launch post, model reference, API changelog, and pricing page establish the usable contract.
The API model ID is gpt-6.1-sol. It has a 1,050,000-token context window, 128,000-token maximum output, and an April 30, 2026 knowledge cutoff. It accepts text and image input and produces text. Audio and video are not supported.
Reasoning effort can be set to low, medium, high, xhigh, or max; medium is the default. Unlike some smaller routes, there is no none or minimal setting. Streaming, function calling, and structured outputs are supported. Fine-tuning is not.
The supported tool surface includes web search, file search, image generation, Code Interpreter, hosted shell, apply_patch, skills, computer use, MCP, and tool search. The important contract detail is that tool calling requires the Responses API. Chat Completions can use the model without that tool plane.
At launch, GPT-6.1 Sol was available in the API and in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu. It was not yet presented as a normal Chat model. US and EU data residency are documented for standard service, while Fast is not available in the EU.
Contract | GPT-6.1 Sol at launch | Production implication |
|---|---|---|
Context / output | 1.05M / 128K tokens | Large enough for repositories and document sets, but pricing changes above 272K input. |
Modalities | Text and image input; text output | Route audio and video through separate transcription or media models. |
Reasoning | Low through max; medium default | Effort is part of the route. Compare it explicitly rather than accepting the default everywhere. |
Tool API | Responses API required for tool calling | A Chat Completions text test does not validate the production agent path. |
Residency | US and EU standard; no EU Fast | Do not make latency-tier decisions independently of data-location policy. |
Fine-tuning | Not supported | Use prompts, tools, retrieval, skills, or routing instead of assuming a custom checkpoint path. |
The pricing looks familiar until the cache starts working
For standard requests with no more than 272K input tokens, GPT-6.1 Sol costs per million tokens:
fresh input     $2.00
cached input    $0.10
cache write     $2.50
output         $10.00
That $2/$10 headline matches GPT-6 Sol from the prior week. The cache read does not. GPT-6 Sol launched at $0.20 per million cached tokens; GPT-6.1 Sol halves it to $0.10.
That matters inside an agent repeatedly reading the same repository map, policy corpus, instructions, schemas, or research packet. A cached token costs one-twentieth of a fresh input token.
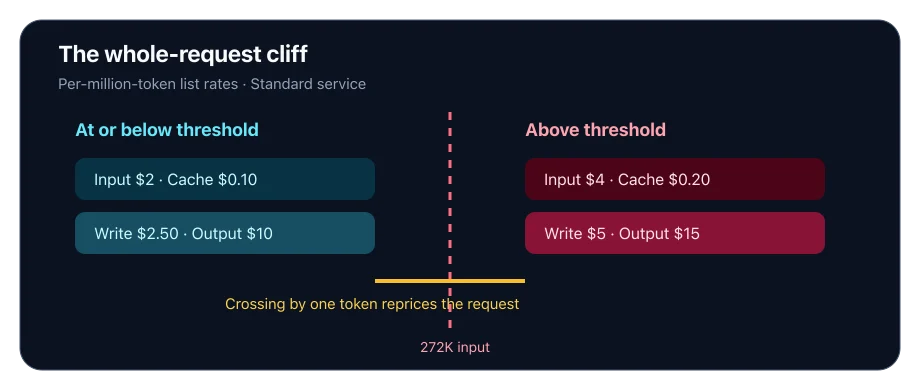
This is not a marginal surcharge on tokens after 272K. Once input crosses the threshold, the long-context rates apply to the full request.
A cache example that is worth doing on paper
Consider one standard short-context run with 200K tokens of reusable project context, 30K fresh input, and 10K output.
With a warm cache:
200K cached input × $0.10/M = $0.02
 30K fresh input  × $2.00/M = $0.06
 10K output       × $10.00/M = $0.10
total                            $0.18
If all 230K input tokens were fresh, the same arithmetic would be $0.56. That is a 68 percent difference before tools and retries. The first cache-writing call is more expensive, so the gain depends on reuse. The point is not that every request becomes cheap. It is that prefix stability becomes an economic feature.
Teams should version and reuse the large stable prefix, then append changing task state. Repacking the same repository or evidence bundle on every turn can erase one of the model's strongest price advantages.
The 272K cliff can overpower a small quality gain
The model reference applies long-context rates when input exceeds 272K tokens. At that point input and cache categories double, while output rises by 50 percent. The full request is repriced.
A simple comparison shows why this belongs in preflight logic:
270K fresh input + 30K output = $0.54 + $0.30 = $0.84
280K fresh input + 30K output = $1.12 + $0.45 = $1.57
Ten thousand extra input tokens make this illustrative bill 87 percent larger because the request crosses the tier boundary. These are list-price calculations, not predicted invoices; actual cache use, reasoning output, tool fees, and retries change the bill.
That makes retrieval and compaction discontinuously valuable. A context manager that keeps a request just under the threshold may save more than a model-router tweak. But blindly truncating context can lower acceptance enough to lose the saving. The right policy is an eval-backed choice among full context, retrieval, summary, or multiple smaller passes.
Budget boundary: Count before you send, not after the invoice
Add a preflight meter for input tokens, cache eligibility, expected output, tool charges, and service tier. When a request approaches 272K, make the routing system choose deliberately between full long context, retrieval, compaction, or a staged workflow.
How to read OpenAI's benchmark claims
OpenAI's launch case is not based on one academic score. It emphasizes end-to-end software engineering, professional work, automation, computer use, scientific terminal tasks, and factuality. That is the right category of evidence for an agent model because an agent can be expensive even when its tokens are cheap.
But the source is still the model vendor. At the September 29 cutoff, RohitAI did not have a matched independent evaluation that justified declaring GPT-6.1 Sol the universal winner. Harnesses, reasoning settings, fallback rules, task sets, and cost accounting can all move an agent benchmark.
Benchmark snapshot
Area | Result | Group | Why it matters |
|---|---|---|---|
DeepSWE 1.1 | Near Astra at about 1/5 task cost | Software engineering | OpenAI reports a 6.4-point gain over the best GPT-6 Sol setting. This is evidence for testing real repository tasks, not proof of universal coding leadership. |
GDP.pdf | Above Opus 5.5 (including its fallbacks) at under half task cost | Professional documents | OpenAI says performance approaches Astra at roughly one-fifth task cost. Document mix and fallback behavior still matter. |
AutomationBench | +2.2 points vs Opus 5.5 medium | Automation | The reported task cost is about one-third of that comparison and the result is 4.8 points above GPT-6 Sol at the same setting. |
OSWorld 2.0 offline | +7 points vs GPT-6 Sol max | Computer use | OpenAI reports under half the task cost and a result within 2.1 points of Astra at around one-seventh the cost. |
Terminal-Bench Science 0.1 | $5.47 per task at max | Scientific terminal work | OpenAI reports more than double GPT-6 Sol max at under half cost. Astra remains highest at 68.1%, while Astra and Opus cost about $23.80 and $23.21 per task. |
Difficult flagged chats | 11.4% to 7.7% factual-error rate at low | Factuality | About a 32% relative reduction on OpenAI's difficult-case set; across tested settings, Sol 6.1 is reported within 1.9 points of Astra. |
Three cautions keep these numbers useful.
First, “task cost” includes the harness's tokens and tool steps. It is more relevant than token price but less portable to your system.
Second, “near Astra” does not mean identical. A small success-rate difference can dominate economics in a workflow where failure triggers an hour of expert review or a costly external action.
Third, a fallback benchmark evaluates a system, not an isolated checkpoint. That can be good product design, but it must be named.
Evidence standard: Promising enough to test; not independent enough to crown
OpenAI's results support a serious production eval. They do not support an unsourced claim that GPT-6.1 Sol beats every competitor or replaces Astra everywhere. Keep the launch numbers labeled as vendor-run and publish your own acceptance criteria.
The new routing math is outcome-shaped
The cheapest route is not necessarily the lowest per-token model. The strongest route is not necessarily the most economical. A useful router estimates this instead:
expected task cost =
  inference + tools + retries + review + failure recovery

expected value per route =
  accepted outcomes × value of success - expected task cost
That formula exposes GPT-6.1 Sol's real opportunity. It can win between Luna and Astra if it eliminates enough retries or review to justify more spend than Luna while preserving most of Astra's completion quality at much lower cost.
Cheap cached input also changes which stage should use Sol. In a long-running agent, the planner or reviewer often rereads a large stable state. That can make Sol attractive for repeated high-judgment checkpoints even when a cheaper model performs bulk execution. The best route may therefore be Sol repeatedly reviewing cached state, not Sol doing every token of work.
Luna route: Bounded, reversible volume
Use the cheaper route for extraction, fan-out, candidate generation, test creation, and well-specified actions that are easy to verify or retry.
GPT-6.1 Sol route: Repeated judgment over stable context
Test it for planning, repository-scale reasoning, hard document work, recovery, and review where cached context and fewer failures can change task economics.
Astra route: The expensive unresolved edge
Keep Astra for tasks where your evals show a material acceptance or safety advantage and the cost of failure justifies the premium.
Human gate: Irreversible or accountable action
Model confidence is not authority. Require a person or deterministic policy before money movement, destructive changes, access grants, or regulated decisions.
Ultrafast is a separate purchasing decision
DevDay also introduced Ultrafast service. In the API, the documented launch call uses GPT-6 Astra with service_tier: "ultrafast" in the Responses API.
OpenAI's recap describes up to six times API speed and up to eight times speed or roughly 300 tokens per second in Codex. The general API guide says up to eight times standard. Those statements are not identical, so production planning should use measured latency for a specific route rather than a single keynote multiplier.
The list price makes the trade clear. For Astra at short context, Ultrafast costs $60 input, $6 cached input, $75 cache write, and $300 output per million tokens. At long context it costs $120, $12, $150, and $450. That is six times Astra's standard list rate.
In other words, the claimed acceleration and price premium are of roughly the same order. Ultrafast is not a free optimization. It is a way to buy wall-clock time when latency has direct business value.
Ultrafast was broadly available through the API at low default limits: 500K tokens per minute for tiers 1 through 3, 1M for tier 4, and 5M for tier 5. It supports Global and US residency, not EU or other regional residency. OpenAI recommends WebSockets for tool-heavy workloads to reduce repeated connection overhead.
GPT-6.1 Sol Ultrafast was announced as coming soon. No Sol Ultrafast price was listed at the cutoff. Do not apply Astra's price or promise Sol's availability by analogy.
Lane | Input | Cache read | Cache write | Output | Status |
|---|---|---|---|---|---|
Sol 6.1 Standard ≤272K | $2 | $0.10 | $2.50 | $10 | Live |
Sol 6.1 Standard >272K | $4 | $0.20 | $5 | $15 | Live |
Astra Ultrafast ≤272K | $60 | $6 | $75 | $300 | Live |
Astra Ultrafast >272K | $120 | $12 | $150 | $450 | Live |
Sol 6.1 Ultrafast | — | — | — | — | Coming soon; unpriced |
All figures are dollars per million tokens. Fast service is separately priced at two times the standard lane. Batch and Flex are 50 percent below standard, while regional processing adds 10 percent according to the pricing documentation. Confirm the current table before deployment because service tiers are particularly likely to change.
Pro 500 bundles speed, not proof of value
The new ChatGPT Pro tiers documentation lists Pro 500 at $500 per month. OpenAI's recap says it carries 25 times the Plus allowance, and the Help Center says it includes Astra Ultrafast. Pro 100 and Pro 200 do not include Ultrafast at launch, and buying credits on those plans does not unlock it.
This tier fits heavy operators whose bottleneck is waiting for Work or Codex. “Included” does not remove opportunity cost, rate limits, or the need to route.
Evaluate Pro 500 with time saved per accepted task:
monthly value =
  accepted tasks accelerated
  × minutes saved per task
  × value of operator time
  - added subscription cost
Do not justify it with tokens you could theoretically consume. Justify it with blocked work that actually becomes faster.
A clean API starting point
For a new integration, use the Responses API and make reasoning effort explicit. This minimal JavaScript example intentionally leaves tools out so the first comparison isolates model behavior:
import OpenAI from 'openai';

const client = new OpenAI();

const response = await client.responses.create({
  model: 'gpt-6.1-sol',
  reasoning: { effort: 'medium' },
  input: 'Review this migration plan. Return risks, missing tests, and a go/no-go recommendation.'
});

console.log(response.output_text);
Then add production tools, schemas, and approvals in a second eval. Capture response IDs, model and service tier, token usage, tool calls, retries, elapsed time, approval events, and the final acceptance decision.
The seven-day migration plan
Do not replace GPT-6 Sol in one deployment. Run a short controlled migration that keeps the old route available for replay.
Seven days from curiosity to a routing decision
Day 1 — Freeze 50 to 100 representative tasks, define acceptance before seeing results, and tag tasks by difficulty, context size, tool use, and failure cost
Day 2 — Replay the current GPT-6 Sol or Luna route and capture outcome, latency, retries, tool errors, cache usage, tokens, review minutes, and total cost
Day 3 — Run GPT-6.1 Sol at low, medium, and the one higher effort most relevant to your workload; keep prompts, tools, and stop rules fixed
Day 4 — Test cold and warm cache paths separately, including one stable-prefix design and one representative request near each side of the 272K boundary
Day 5 — Run adversarial failures: unavailable tool, malformed tool output, stale evidence, conflicting files, long recovery loop, refusal, timeout, and interrupted stream
Day 6 — Have reviewers grade blind, then calculate accepted outcomes per dollar and per minute rather than comparing style or benchmark reputation
Day 7 — Promote only the task classes that pass; set budgets and fallback rules, keep a canary, and record the exact model, effort, service tier, and prompt version
A good result may be a partial migration. Sol 6.1 could win repository review and document synthesis while Luna keeps extraction and Astra keeps a narrow set of costly edge cases. That is not indecision. It is routing.
What could change after launch
Several details were still moving at the research cutoff.
GPT-6.1 Sol Ultrafast was announced but not live or priced. Independent labs had not yet supplied a broad matched verdict. Product rollouts can lag documentation by account or region. OpenAI's API changelog labels multi-agent support beta. Ordinary Chat availability was not announced. And session recordings from DevDay were still pending while this analysis was prepared.
Those are reasons to timestamp the conclusion, not to ignore the release.
As of September 29, the evidence supports three actions: benchmark GPT-6.1 Sol seriously, redesign stable context for cache reuse, and make the 272K threshold visible in routing. It does not support deleting every other model route.
FAQ
How much does GPT-6.1 Sol cost?
For standard API requests up to 272K input tokens, OpenAI lists $2 per million fresh input tokens, $0.10 cached input, $2.50 cache writes, and $10 output. Above 272K input, the whole request uses $4, $0.20, $5, and $15 rates respectively.
Is GPT-6.1 Sol cheaper than GPT-6 Sol?
Fresh input and output launch rates are the same at $2/$10 for standard short-context use. The major direct tariff improvement is cached input, which falls from $0.20 to $0.10 per million tokens. Real task cost can also change because the models may consume different tokens, steps, and retries.
Is GPT-6.1 Sol as good as GPT-6 Astra?
OpenAI reports near-Astra results on several evaluations at substantially lower task cost, but not parity everywhere. Astra remains ahead in at least some launch results, including Terminal-Bench Science 0.1. There was no independent universal verdict at the research cutoff.
Does GPT-6.1 Sol support tools and computer use?
Yes. Its documented tool surface includes computer use, web and file search, code execution, hosted shell, MCP, skills, and other tools. Tool calling requires the Responses API.
What happens above 272K tokens?
The threshold is based on input tokens. Once input exceeds 272K, the full request moves to the long-context rates: input and cache categories double and output becomes 1.5 times the short-context rate. It is not marginal pricing only on the excess.
Is GPT-6.1 Sol Ultrafast available?
Not at the September 29 launch cutoff. OpenAI said it was coming soon. Astra Ultrafast was live, with separate pricing and Global/US residency only.
Should I buy Pro 500 for GPT-6.1 Sol?
Only if the higher allowance and included Astra Ultrafast save enough time on accepted Work or Codex tasks to justify $500 per month. Pro 500 economics are subscription and workflow economics, not the same as API token pricing.
Final take
GPT-6.1 Sol is a more interesting release than its unchanged $2/$10 headline suggests.
It makes stable context cheaper to reread. It makes Astra-like outcomes plausible for more workflows. It pushes task cost, not token cost, into the center of the model decision. And it arrives beside an acceleration lane expensive enough to force an explicit value-of-time calculation.
The best migration is therefore not a global model-name replacement.
Put GPT-6.1 Sol into the routes where judgment repeats over large, reusable context. Keep Luna on cheap, bounded work. Keep Astra only where it wins a meaningful edge. Add human authority where the action is irreversible. Count the request before the 272K cliff. Measure review and retries after it runs.
Seven days ago, “build for acceptance” was the right advice. GPT-6.1 Sol does not overturn it.
It makes the acceptance calculation more favorable—and more demanding.